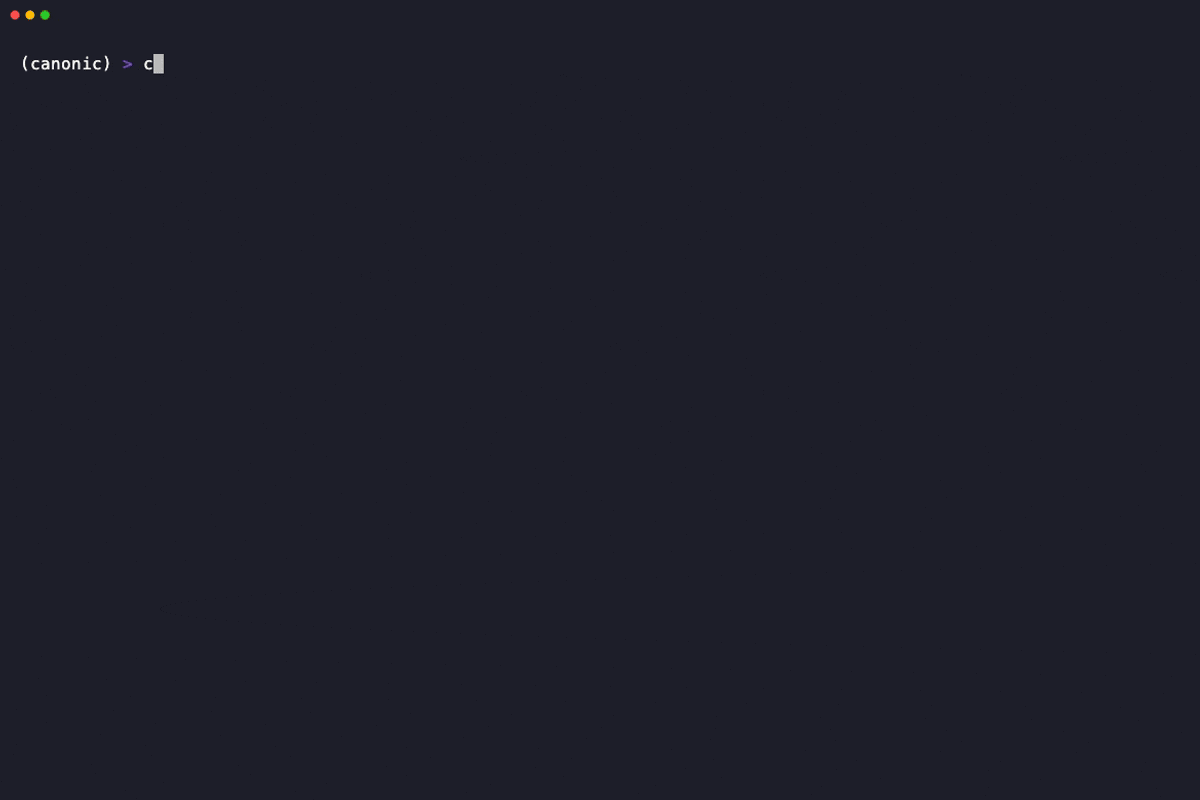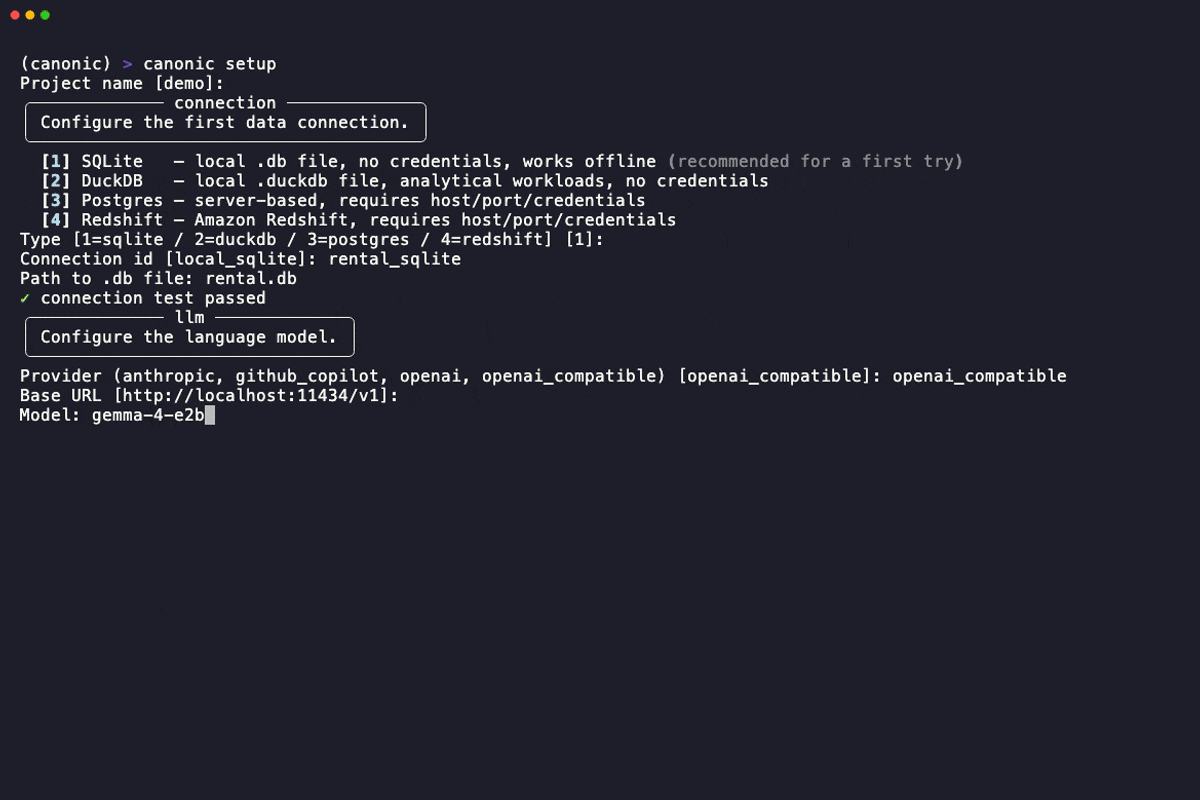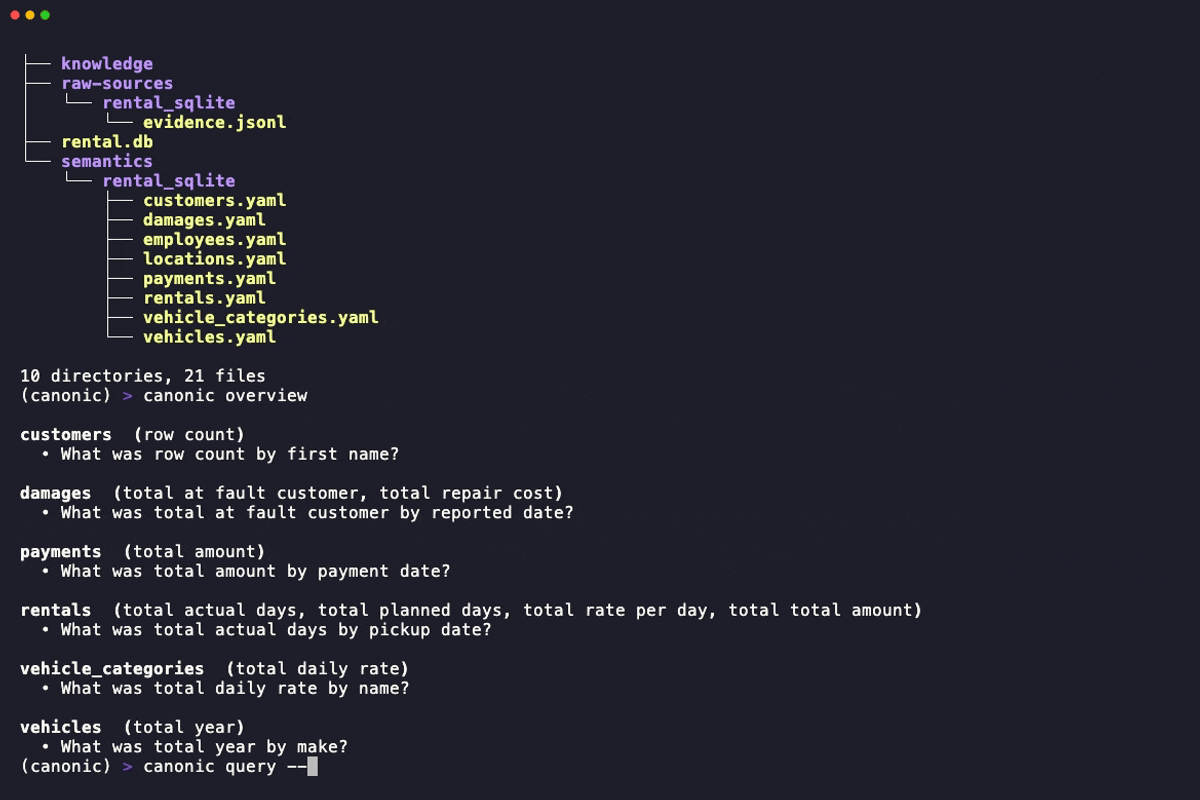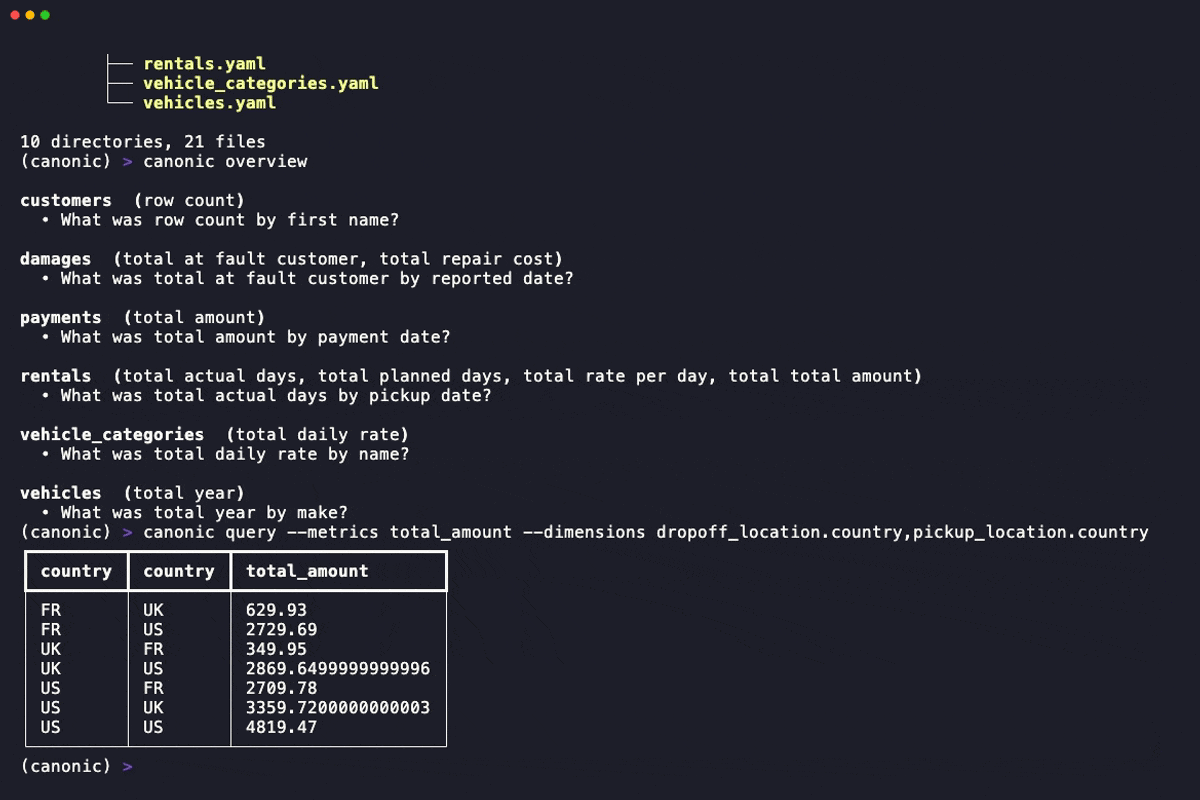
canonic setup end-to-end on the vehicle rental example.
Don’t have a database handy? The Guides section ships 5 ready-to-run sample projects (dbt Jaffle Shop, e-commerce, rental, SaaS analytics, Dutch railway), a good way to try the wizard before pointing it at your own data.
- SQLite
- DuckDB
Point at a local
.db file:What the wizard does
1
Name your project
Give your canonic project a name.
2
Connect a source
SQLite/DuckDB file, or Postgres, MySQL, ClickHouse, Redshift, Snowflake or Databricks if you have a server or account.
3
Configure an LLM (optional)
Skippable: the core works without one. See Configuring an LLM.
4
Bootstrap
canonic introspects the schema and drafts your semantics.
5
First answer
The wizard runs a real query against your data and shows the result, plus how fresh it is and which definition it used.
Ask your own questions
You now have a working context layer committed to your repo:revenue with a metric that actually exists in your project. Run canonic status to see what’s available.
For a query with more filters or joins than is comfortable inline, write a SemanticQuery JSON file and pass it with -f instead. See canonic query for the full flag reference.
Review what canonic drafted
It’s all an ordinary git diff:Out of the box vs. a bit more effort
Works immediately, zero modeling:- Connect a database (SQLite, Postgres, Snowflake and others) and canonic introspects the live schema.
- It auto-drafts semantics: typed columns, primary-key grains, foreign-key joins, and additive measures (sums, counts).
- The setup wizard ends by answering a real question from your data, so you see the payoff in minutes.
- Connect your agent over MCP and start asking.
- Canonical bindings: when two sources define “revenue” differently, you pick the authoritative one. canonic surfaces the ambiguity. You resolve it once.
- Knowledge prose: the business “why” behind a definition. canonic drafts it, you refine it.
- Guardrails & contracts: mandatory filters, required dimensions, final-vs-provisional rules. Added when a number needs protecting.
- Non-additive metrics: ratios, averages, distinct counts, balances. Declared as composable definitions so they stay correct at any grain.
- More sources: dbt / Metabase / Notion / web pages, layered on as context evidence. The connector contract is extensible, so a Confluence, Jira, or other wiki/knowledge-base connector can be added the same way.
See the end-to-end example for the full loop in one place:
ingest → review → apply, what happens when your data actually changes, defining a canonical metric and guardrail by hand, and running the same loop headless in CI.